Nebius × NVIDIA Global AI Hackathon

Agent Joules

Which agent step burns the most energy?

GPU energy per agent step, measured on your GPUs. Agent Joules wraps each agent of a Microsoft Agent Framework workflow in a metered chat client that records tokens, latency and cost for every model call, and on a GPU you control, joules and watts through NVML.

Hackathon prototype · MIT licensed · Every measured number in the text of this page comes from a committed results file.

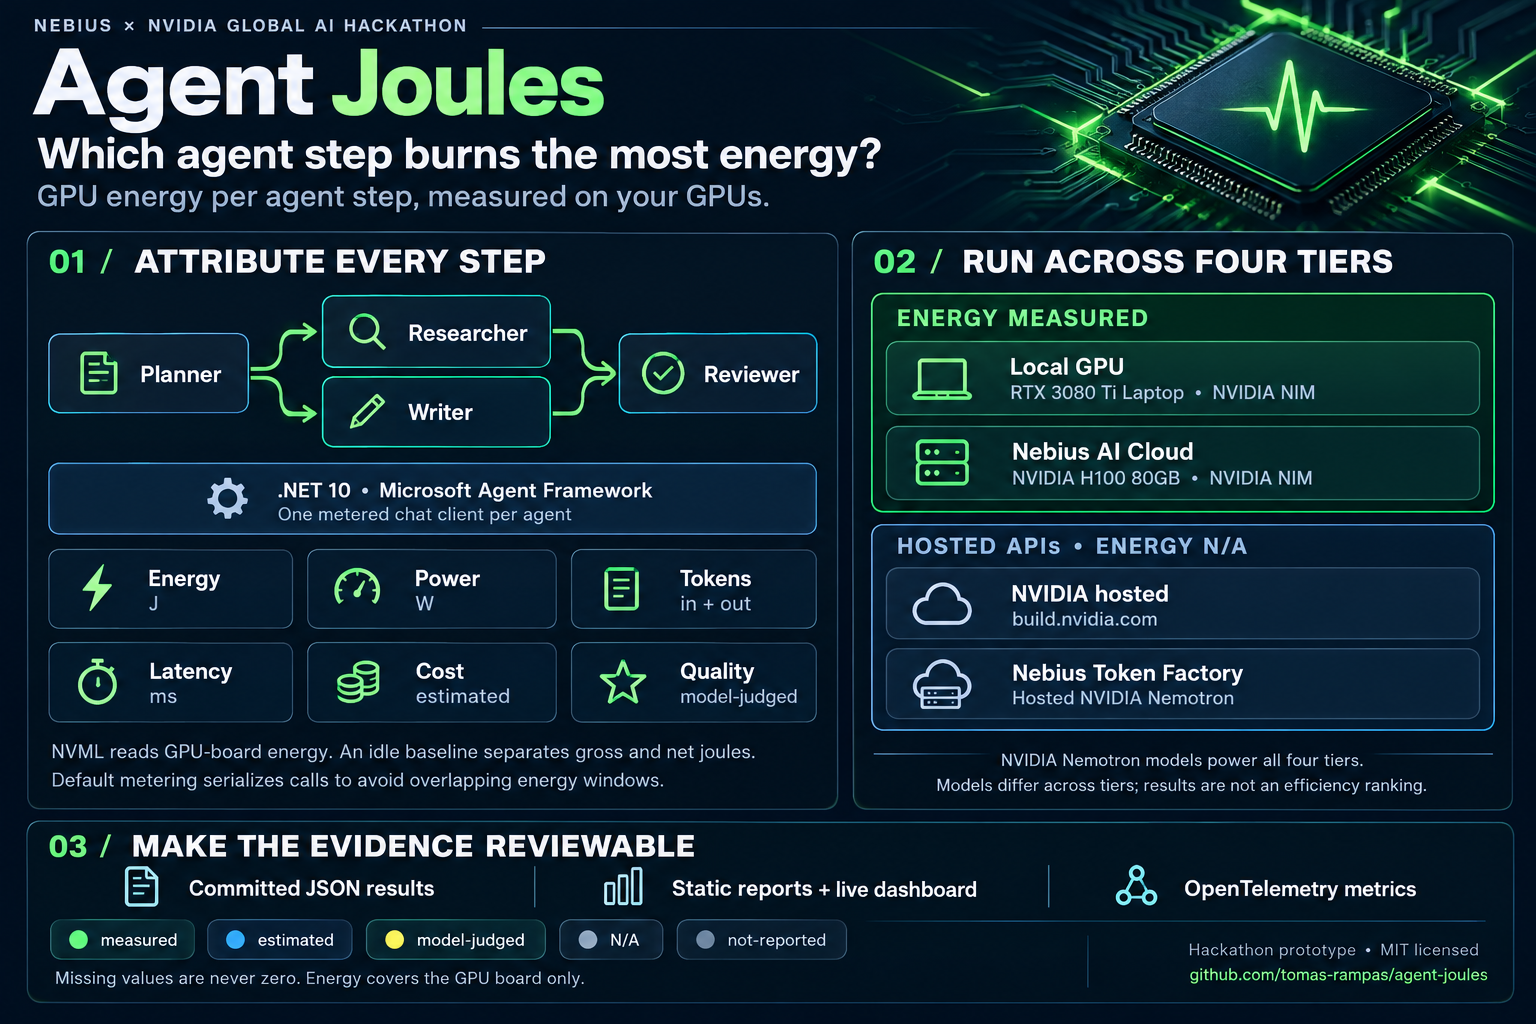
Infographic: Agent Joules attributes energy, power, tokens, latency, cost and quality to every step of a Planner, Researcher, Writer, Reviewer workflow, runs across four NVIDIA Nemotron tiers and keeps the evidence reviewable.
Agent Joules at a glance

How it works

01 /Attribute every step

.NET 10 · Microsoft Agent Frameworkone metered chat client per agent
EnergyJ
PowerW
Tokensin + out
Latencyms
Costestimated
Qualitymodel-judged

NVML reads GPU-board energy. An idle baseline separates gross and net joules. Default metering serializes calls to avoid overlapping energy windows.
02 /Run across four tiers

Energy measured

Local GPURTX 3080 Ti Laptop · NVIDIA NIM
Nebius AI CloudNVIDIA H100 80GB · NVIDIA NIM

Hosted APIs · energy N/A

NVIDIA hostedbuild.nvidia.com
Nebius Token Factoryhosted NVIDIA Nemotron

NVIDIA Nemotron models power all four tiers. Models differ across tiers; results are not an efficiency ranking.

03 /Make the evidence reviewable

  • Committed JSON results
  • Static report + live dashboard
  • OpenTelemetry metrics
  • measured
  • estimated
  • model-judged
  • N/A
  • not-reported

Missing values are never zero. Energy covers the GPU board only.

Results

One workflow, three tasks, three repeats per tier. Run totals from the committed results files; energy is GPU-board energy only, judge calls excluded.

local

GPU NVIDIA GeForce RTX 3080 Ti Laptop GPU

nvidia/Llama-3.1-Nemotron-Nano-4B-v1.1 (BF16, NIM 1.8.5)

33134.2 Jnet energy
Run date
2026-10-27
Gross J
43906.6
Input tokens
25770
Output tokens
17556
Cost
0.0028 EUR estimated
  • measured
  • estimated

cloudgpu

GPU NVIDIA H100 80GB HBM3 (Nebius AI Cloud, preset 1gpu-16vcpu-200gb)

nvidia/nemotron-3-nano (FP8)

10389.6 Jnet energy
Run date
2026-10-26
Gross J
16364.1
Input tokens
25379
Output tokens
15889
Cost
0.0647 USD estimated
  • measured
  • estimated

nvidia

hosted build.nvidia.com

nvidia/nemotron-3-nano-omni-30b-a3b-reasoning

N/Anet energy (hosted-tier)
Run date
2026-10-25
Gross J
N/A (hosted-tier)
Input tokens
25550
Output tokens
16548
Cost
N/A (no priced step)
  • measured
  • N/A

nebius

hosted Nebius Token Factory

nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B

N/Anet energy (hosted-tier)
Run date
2026-10-25
Gross J
N/A (hosted-tier)
Input tokens
26554
Output tokens
16991
Cost
0.0057 USD estimated
  • measured
  • estimated
  • N/A

Models differ across tiers: local nvidia/Llama-3.1-Nemotron-Nano-4B-v1.1 (BF16), cloudgpu nvidia/nemotron-3-nano (FP8), nvidia nvidia/nemotron-3-nano-omni-30b-a3b-reasoning, nebius nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B. The quality judge is nvidia/nemotron-3-nano-omni-30b-a3b-reasoning on the nvidia tier.

Full per-step tables and chart in the static report →

The live dashboard

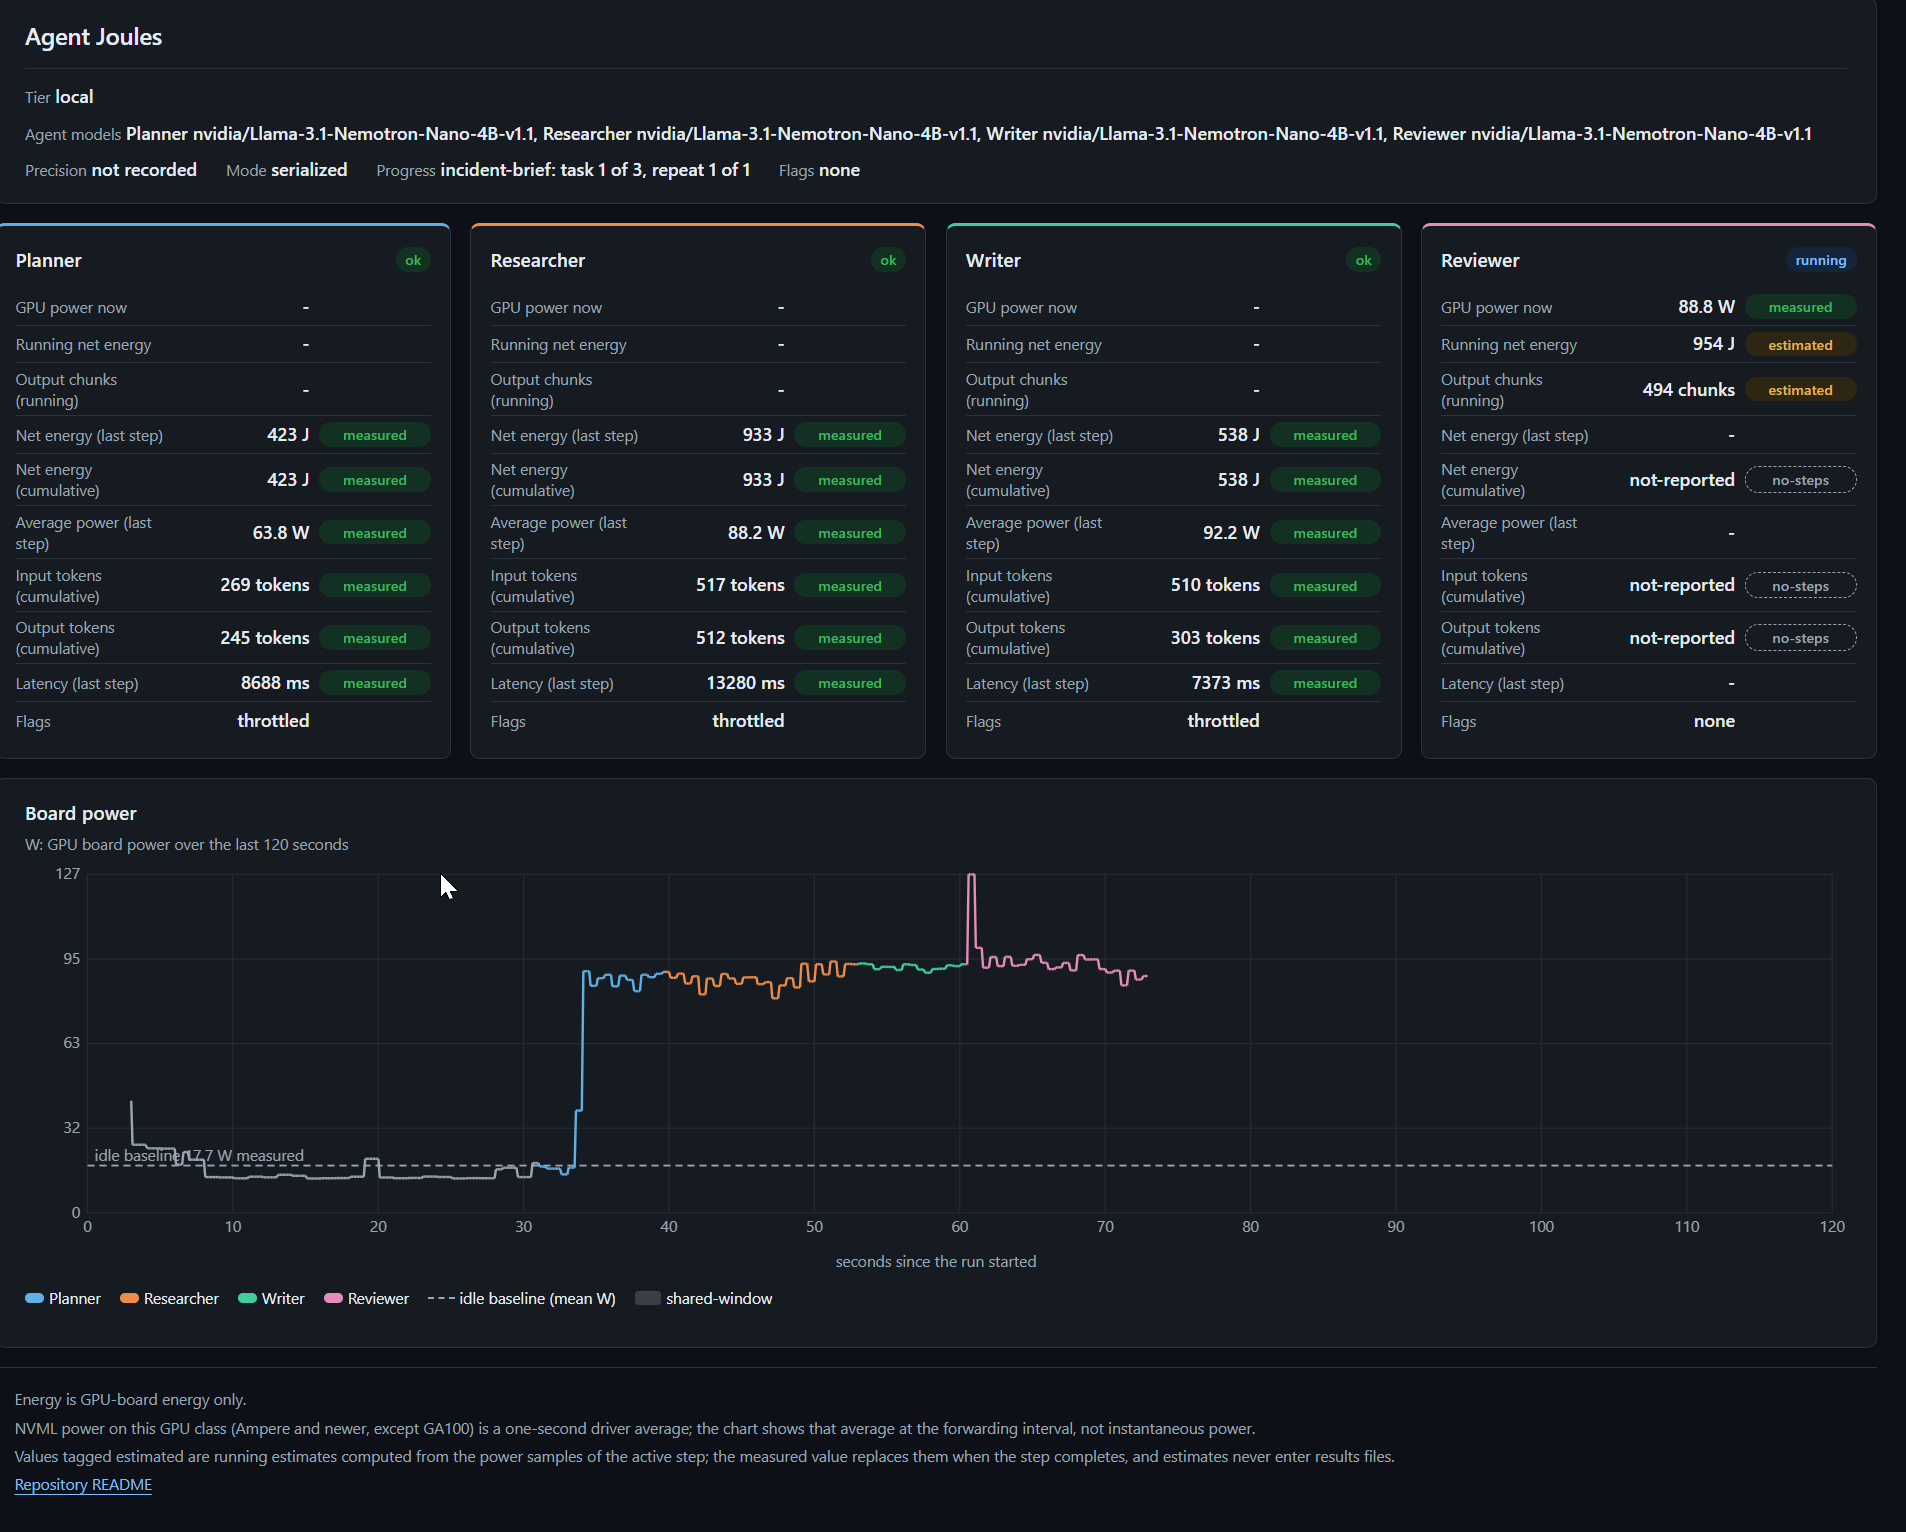
Agent Joules live dashboard in dark theme: one card per agent with GPU power, net energy, tokens and latency, and a GPU board power chart coloured by active agent.
The dashboard during a three-task rehearsal run on the local tier: one card per agent with GPU power now, running net energy, tokens and latency, each value carrying its label, and GPU board power over the last 120 seconds coloured by the active agent above the measured idle baseline. Values tagged estimated are running estimates and never enter results files. The run file of this rehearsal is git-ignored and outside results/, so none of the figures in the image is in a committed results file; the committed runs are in the static report.

To see the page without installing anything, open the hosted replay, which plays the committed cloudgpu and local runs in the browser with no key and no server. Replay without a GPU or key:

dotnet run --project src/AgentJoules.Cli -- dashboard --replay results/20261026T124721Z-cloudgpu.json --speed 4 --exit-after 60

Nemotron and Nebius

How it uses NVIDIA Nemotron

  • local nvidia/Llama-3.1-Nemotron-Nano-4B-v1.1 served by an NVIDIA NIM container on the laptop GPU.
  • cloudgpu nvidia/nemotron-3-nano served by an NVIDIA NIM container on a Nebius AI Cloud VM with one NVIDIA H100 80GB.
  • nvidia nvidia/nemotron-3-nano-omni-30b-a3b-reasoning on the hosted build.nvidia.com endpoint.
  • nebius nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B on the Nebius Token Factory endpoint.

Where Nebius came in

The nebius tier calls Nebius Token Factory, which served nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B for the whole workflow: a hosted comparison tier with no GPU to own or rent, measured for tokens, latency and cost from a laptop with a key alone.

The cloudgpu tier ran on one Nebius AI Cloud GPU VM (preset 1gpu-16vcpu-200gb, region eu-north1) where the NIM container and the NVML meter share one H100; rental 1.509 GPU-hours (estimated) at USD 4.63 per hour (the console price), about USD 7 for the whole rental window (estimated; docs/cloudgpu-run.md), VM deleted after the run.

Judges without a GPU: four actions, no key needed

  1. dotnet test runs the unit tests.
  2. dotnet run --project src/AgentJoules.Cli -- validate results/ checks the committed results files against the schema and prints Validated <n> files.
  3. Open the hosted replay at replay/ (the live dashboard page replaying the committed cloudgpu and local runs in the browser, no key) or docs/report/index.html, the committed report page.
  4. Run the dashboard replay command:
    dotnet run --project src/AgentJoules.Cli -- dashboard --replay results/20261026T124721Z-cloudgpu.json --speed 4 --exit-after 60

Honesty rules

Five labels, never zero

measured, estimated, model-judged, N/A, not-reported. A missing value is never written as zero.

Generated, not typed

The README results block is generated from the committed results files by report --update-readme.

GPU board only

Energy is GPU-board energy. Judge calls are excluded from workflow totals. Models differ across tiers and are not ranked.